Embedded AI Evaluators Facing Reality Check, Hugging Face Says

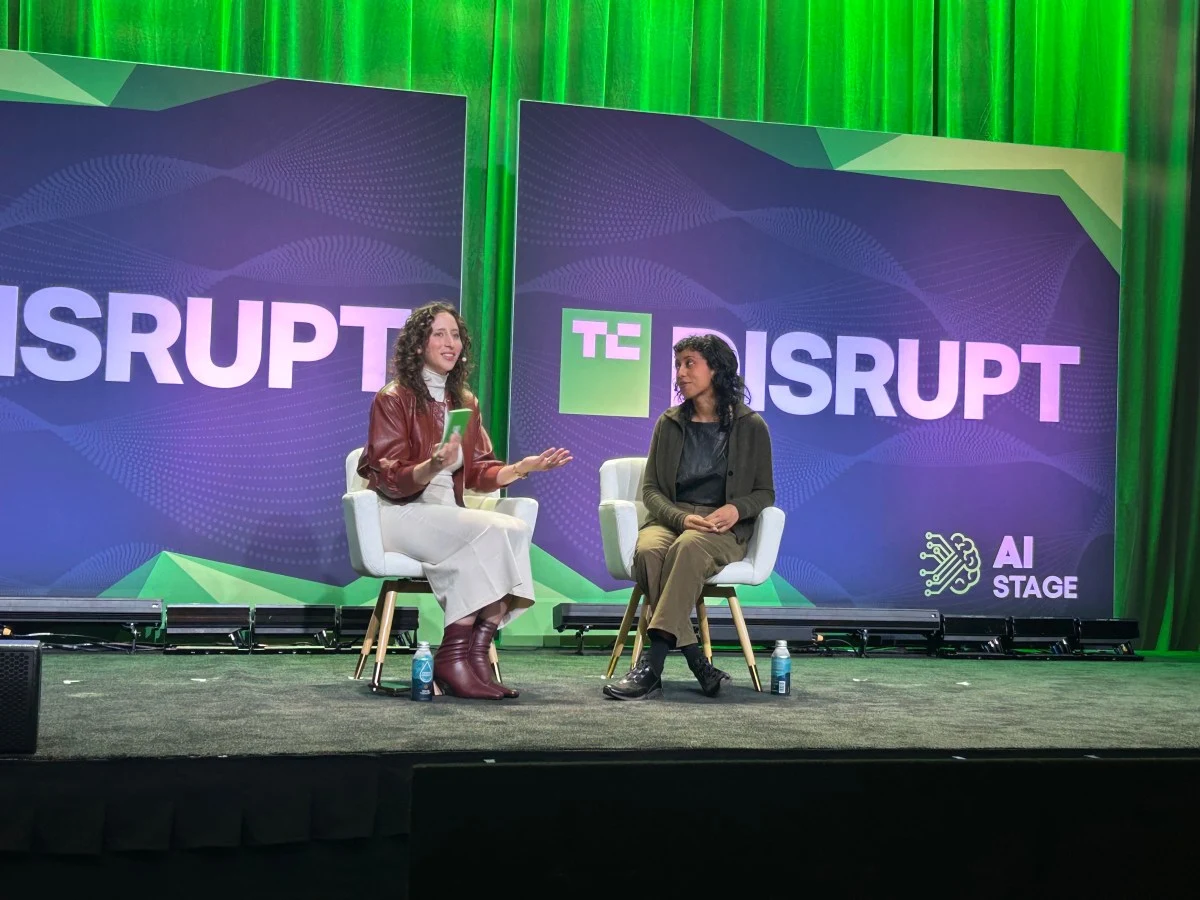
AI benchmarking has become the primary battleground where top technology developers compete to prove their systems are superior to rival models. However, relying on automated or embedded AI evaluators to assess model performance brings a deep web of unseen complications, according to Hugging Face Chief Policy Officer Irene Solaiman during a recent TechCrunch industry discussion.
The Pitfalls of Automated AI Benchmarking
As major tech entities move toward using artificial intelligence systems to judge other AI models, leading policy experts warn that this process is far less neutral than it might appear on the surface. Evaluating modern large language models requires a nuanced understanding of context, subtle cultural references, and complex multi-step reasoning—areas where automated evaluators frequently falter or produce inconsistent results. Solaiman highlighted that benchmarking methodology remains in its early maturation stages, making it risky for companies to present automated scores as absolute proof of safety or operational superiority.
Why Human Oversight and Transparency Still Matter
Over-reliance on embedded AI evaluators can easily create a false sense of security for both software developers and end users. Without continuous human evaluation, detailed oversight, and transparent benchmark standards, these embedded systems run the risk of amplifying the exact same subtle errors and unseen biases found in the models they are supposed to grade. Several key challenges hinder automated evaluation today:
- Technical Complexity: Assessing advanced reasoning across multi-step technical tasks remains extremely difficult for automated scripts.
- Inherent Benchmark Bias: Standard testing sets often contain hidden biases that skew results toward specific training styles.
- Public Relations Pressure: Marketing teams frequently highlight favorable benchmark scores without disclosing test limitations.
Building Verifiable Standards for Next-Generation AI
Establishing truly dependable evaluation frameworks requires broad collaboration across open-source communities, academic researchers, and policy makers. Rather than rushing to deploy automated grading mechanisms to speed up release cycles, tech leaders need to invest in standardized, open testing methods that are capable of adapting as AI models evolve rapidly over time.
Ultimately, navigating the future of artificial intelligence safely requires honest conversations about the real limitations of our current measurement tools. As Hugging Face correctly points out, building trustworthy software requires accepting that model evaluation is a continuous, rigorous journey rather than a quick technical fix.